 Abdullah
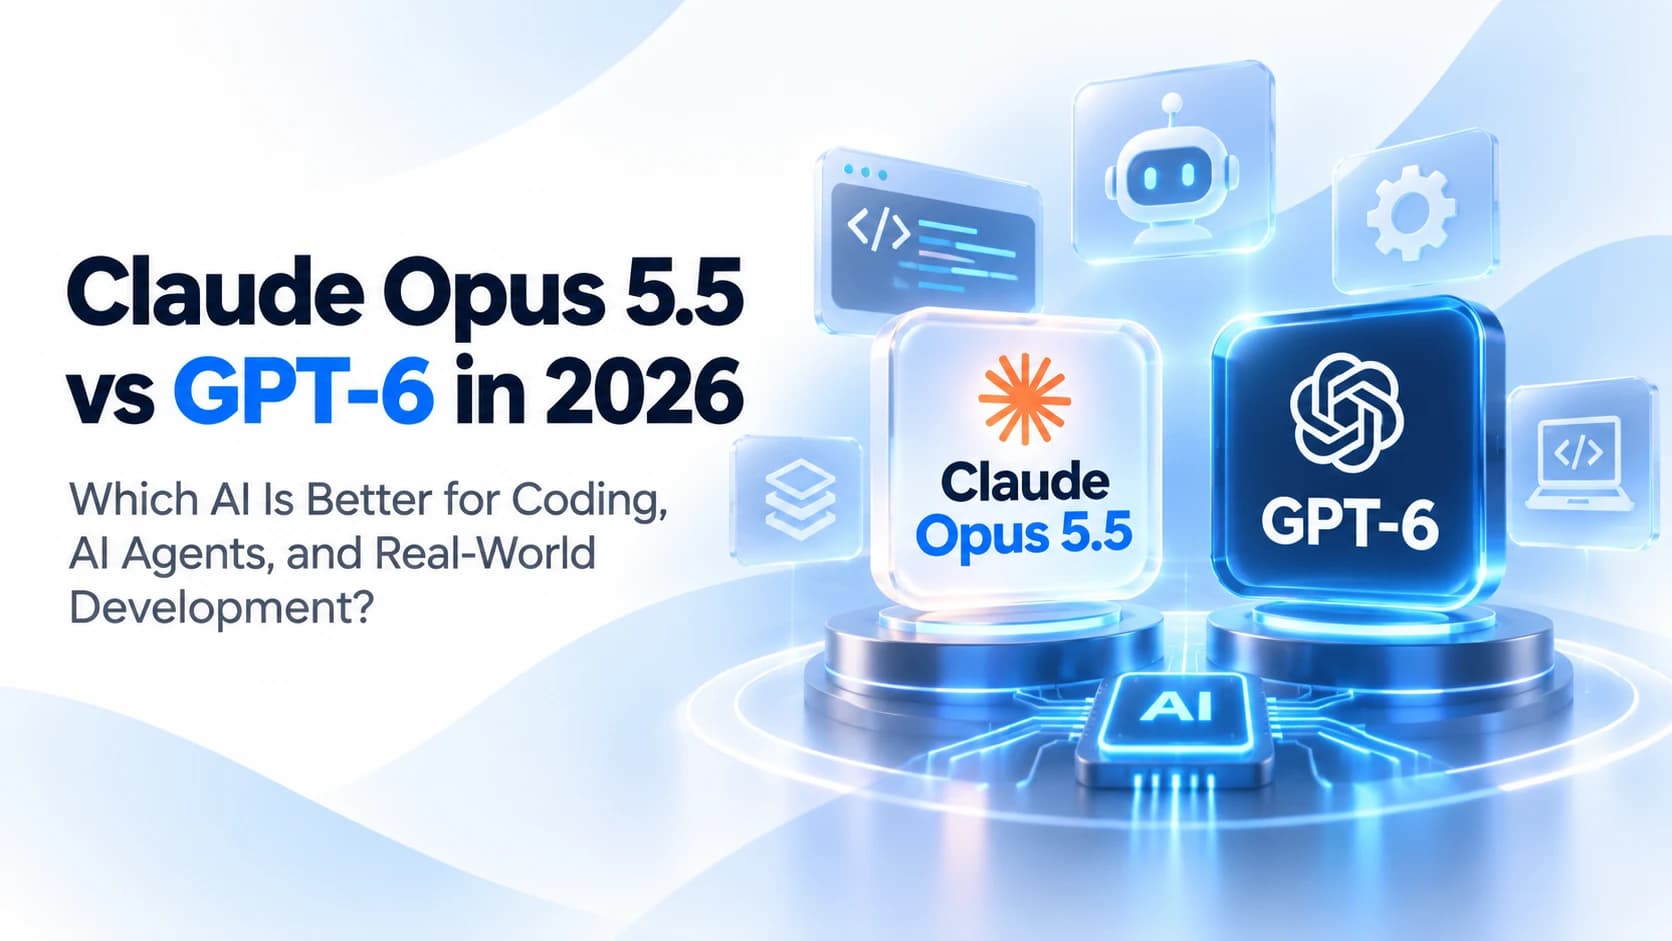
Artificial intelligence is changing how software is built, tested, and maintained. In 2026, the competition between Anthropic and OpenAI has moved beyond chatbots that generate code snippets. Their latest frontier models can investigate complex bugs, navigate large repositories, execute development tools, and complete multi-step engineering tasks.
Two models attracting attention are Claude Opus 5.5 and GPT-6. Both promise stronger reasoning, advanced coding capabilities, and more autonomous AI agents. But for developers, CTOs, and startup founders, the important question is not simply which model performs better on a benchmark. It is which one can help deliver reliable software with less rework, lower operational costs, and fewer production problems.
In this Claude Opus 5.5 vs GPT-6 comparison, we examine coding performance, AI agents, debugging, software architecture, API pricing, context windows, security, and real-world application development. We also explain when each model makes sense and why combining multiple models may be a better strategy than choosing only one.
What Are Claude Opus 5.5 and GPT-6?
Claude Opus 5.5 is Anthropic's advanced reasoning model, released on September 22, 2026. It is designed for demanding software engineering, long-running AI agents, professional workflows, and complex technical tasks. Anthropic positions the model as an improvement in both capability and efficiency, particularly for developers working with large codebases and autonomous coding workflows.
GPT-6 is OpenAI's frontier model family. It includes GPT-6 Astra for demanding reasoning and software engineering, alongside more cost-efficient models such as GPT-6 Sol and Luna. GPT-6 Astra is the most relevant comparison for Claude Opus 5.5 when evaluating advanced coding, complex debugging, and agentic software development.
Both companies are moving toward a similar goal: AI systems that can do more than suggest an answer. These systems can use tools, inspect results, revise their approach, and work through larger tasks. However, the quality of the final outcome still depends on the model, its development environment, the available tools, and the verification process.
Claude Opus 5.5 vs GPT-6: Quick Comparison
The following table compares Claude Opus 5.5 with GPT-6 Astra using published model specifications and documented capabilities. API prices represent standard token rates and may differ under batch processing, fast modes, regional configurations, or long-context pricing.
FeatureClaude Opus 5.5GPT-6 AstraDeveloperAnthropicOpenAIPrimary focusCoding, AI agents, knowledge workAdvanced reasoning, coding, computer useContext window1 million tokens1.05 million tokensMaximum standard output128,000 tokens128,000 tokensAPI input price$4 per million tokens$10 per million tokensAPI output price$20 per million tokens$50 per million tokensCached input price$0.20 per million tokens$1 per million tokensReasoning controlsAdaptive thinking with effort settingsMultiple reasoning-effort settingsCoding environmentClaude Code and supported integrationsCodex and supported integrationsLong-running agentsSupportedSupportedProduction suitabilityRequires engineering validationRequires engineering validation
Claude Opus 5.5 has a significant advantage in standard published token pricing compared with GPT-6 Astra. However, pricing alone does not determine the total cost of a coding task. A model that completes a difficult task with fewer attempts, tool calls, or corrections may cost less overall despite a higher price per token.
1. Claude Opus 5.5 vs GPT-6 for Coding: Which Is Better?
AI coding assistants are now involved in much more than autocomplete. Development teams use them for feature implementation, API integrations, unit testing, database changes, frontend components, code review, and debugging. As these tasks become more complex, the difference between generating working code and producing maintainable software becomes increasingly important.
Claude Opus 5.5 for Software Engineering
Anthropic designed Claude Opus 5.5 for extended engineering tasks, including work that requires understanding multiple files, tracing dependencies, and maintaining consistency across a codebase. Its emphasis on planning, debugging, verification, and communication makes it a relevant choice for teams managing established software products.
Consider a SaaS application built with Next.js, Node.js, and PostgreSQL. A developer needs to introduce subscription upgrades without breaking existing billing workflows. The work may involve backend endpoints, database migrations, frontend states, webhook processing, and regression tests. A capable coding agent needs to understand how these pieces interact rather than implementing each file independently.
Claude Opus 5.5 is designed to support this kind of connected engineering workflow. However, its actual performance depends on the repository, available context, tools, and task complexity. Teams should verify changes through automated tests and engineering review rather than assuming a successful generation is production-ready.
GPT-6 Astra for Complex Coding Tasks
GPT-6 Astra is OpenAI's most capable model for demanding software engineering work. OpenAI highlights improvements in coding benchmarks, multi-step reasoning, computer use, and tool-based execution. Within Codex, Astra also supports an experimental approach to preserving and retrieving context across extended development sessions.
This matters when an engineering task cannot be completed in one attempt. A coding agent might inspect a failing test, identify a dependency issue, modify several modules, run the test suite again, and revisit an earlier assumption. Preserving useful information from previous steps can reduce repeated investigation and help maintain continuity.
GPT-6 Astra is particularly worth evaluating for complex development workflows involving code execution, iterative testing, database changes, and difficult reasoning. Its higher token price makes task-level efficiency an important consideration.
Which Model Wins for Coding?
There is no universal winner across every programming task. GPT-6 Astra demonstrates strong published results on advanced software engineering evaluations, while Claude Opus 5.5 offers competitive capabilities with substantially lower standard API token pricing. The correct choice depends on whether a team values maximum task capability, development speed, cost efficiency, or consistency within its existing tools.
For routine coding, teams should also evaluate smaller models rather than automatically using the most expensive frontier model. For complex refactoring or difficult debugging, testing Claude Opus 5.5 and GPT-6 Astra against the same real repository is a more reliable decision method than relying on marketing claims.
2. Claude Opus 5.5 vs GPT-6 Coding Benchmarks
Benchmarks help developers understand model capabilities, but they require careful interpretation. A benchmark result depends on the model version, evaluation environment, available tools, reasoning settings, and number of attempts. Results from different configurations should not automatically be treated as a controlled head-to-head experiment.
Terminal-Bench 4.0
Terminal-Bench evaluates the ability of AI agents to complete tasks in command-line environments. These tasks can require technical reasoning, tool execution, and multiple steps rather than a single code-generation response.
OpenAI reports a Terminal-Bench 4.0 score of 57.9% for GPT-6 Astra. Its published comparison includes 52.6% for Claude Opus 5, which is an earlier model and must not be confused with Claude Opus 5.5. Anthropic also publishes Terminal-Bench comparisons for Opus 5.5, but the reported evaluation settings and uncertainty should be reviewed before declaring a definitive winner.
DeepSWE: Real Software Engineering Tasks
DeepSWE evaluates models on extended software engineering problems. OpenAI reports GPT-6 Astra scoring 74.1% on DeepSWE v1.1 in its published evaluation. This is relevant because real development frequently requires understanding existing code, making coordinated changes, and validating outcomes.
However, a strong benchmark score does not guarantee that a model will understand every business rule or correctly modify every production system. Development teams still need repository-specific evaluations, test coverage, and human review.
FrontierCode: Beyond Generating Code
FrontierCode examines whether coding agents can produce changes suitable for real software projects. The evaluation considers more than whether a piece of code executes. It also addresses qualities such as test coverage, scope discipline, and compatibility with existing development conventions.
OpenAI reports GPT-6 Astra scores of 64.5% on FrontierCode 1.1 Extended and 53.3% on FrontierCode 1.1 Main. These results illustrate how demanding merge-ready software engineering remains, even for advanced models.
The key lesson is that AI coding performance should be measured by accepted, verified changes rather than the amount of code generated. A model that produces fewer lines but requires less rework may deliver greater business value.
3. Claude Opus 5.5 vs GPT-6 for AI Agents
One of the biggest developments in artificial intelligence in 2026 is the move from conversational AI assistants toward autonomous, tool-using systems. An AI agent can interpret a goal, select actions, interact with software, evaluate results, and continue until it completes a task or requires human intervention.
Businesses are exploring agentic AI for customer support, internal operations, sales workflows, financial analysis, document processing, and software engineering. However, more autonomy also introduces operational risks, particularly when an agent can modify records, spend money, or interact with external systems.
Claude Opus 5.5 for Long-Running AI Agents
Claude Opus 5.5 is built for multi-step agentic workflows, including complex tool orchestration and long-running engineering tasks. Anthropic emphasizes deliberate planning, subagent coordination, memory, and the ability to verify work while progressing through a task.
For example, an engineering agent could investigate a reported API issue, inspect application logs, identify affected services, suggest a code change, and run tests before submitting the result for approval. This workflow requires much more than generating a response from a single prompt.
Claude's agentic capabilities make it a candidate for engineering automation and enterprise workflows where tasks involve multiple dependencies. The system still needs permissions, reliable tool integrations, and approval boundaries.
GPT-6 Astra for Autonomous Workflows
GPT-6 Astra also supports advanced agentic workflows through OpenAI's developer tooling. Its capabilities include tool calling, code execution, file operations, browsing, and computer interaction where supported by the environment.
OpenAI has also emphasized safeguards for autonomous actions, including confirmation mechanisms and monitoring intended to reduce unauthorized or unintended behavior. These controls matter because agent reliability is not simply about completing the task. It is also about avoiding actions that were never authorized.
GPT-6 Astra is a strong candidate for workflows that combine complex reasoning with multiple software tools. GPT-6 Sol and other smaller models may offer a more economical option for high-volume automation where the full capability of Astra is unnecessary.
Which AI Is Better for Building Agents?
Claude Opus 5.5 is worth prioritizing for evaluation when the workflow involves long-running coding tasks, complex repository understanding, and coordinated subagents. GPT-6 Astra is worth prioritizing for evaluation when tasks require advanced reasoning, computer interaction, and integration with OpenAI's tool ecosystem.
Neither model should be treated as automatically safe for unrestricted autonomy. Production AI agents need explicit permission boundaries, action logs, retries, spending limits, and human approval for high-impact operations.
4. Which AI Is Better for Debugging and Fixing Existing Applications?
Debugging is one of the most valuable applications of AI-assisted software development. Writing a new feature is often easier than understanding why an existing system fails under a specific combination of conditions.
Consider an application where customers occasionally receive duplicate bookings. The problem might originate from simultaneous requests, missing database constraints, payment webhook retries, or incorrect transaction handling. Simply asking an AI model to fix duplicate bookings may produce a patch that hides the symptom without addressing the underlying cause.
A stronger engineering process requires the agent to reproduce the issue, inspect the relevant request flow, identify the root cause, propose a focused change, and verify the result under concurrent conditions.
Both Claude Opus 5.5 and GPT-6 Astra are capable candidates for this workflow. Claude's documented focus on root-cause investigation and long-running coding tasks is particularly relevant, while GPT-6 Astra's reasoning and execution capabilities make it useful for iterative debugging and testing.
The deciding factor should be whether the model produces a verified fix with minimal unnecessary changes. For businesses dealing with poorly structured or AI-generated applications, a professional application code review and recovery process can help determine what should be repaired, refactored, or rebuilt.
5. Claude Opus 5.5 vs GPT-6 for Full-Stack Development
Full-stack development requires coordination between user interfaces, backend services, databases, authentication, third-party integrations, and deployment infrastructure. AI models can accelerate parts of this work, but successful implementation depends on preserving consistency across the entire system.
Frontend Development: React, Next.js, and User Interfaces
Both models can assist with React components, Next.js applications, responsive layouts, form validation, and frontend debugging. A practical evaluation should test whether the generated interface follows an existing design system, handles loading and error states, and behaves correctly across screen sizes.
Generating an attractive page is not the same as delivering a usable frontend. Accessibility, navigation, state management, mobile responsiveness, and integration with real APIs all require verification.
Backend Development: Node.js, Python, and APIs
Backend tasks introduce additional complexity because mistakes can affect application security, financial transactions, and data integrity. AI-generated endpoints may appear correct while overlooking authorization checks, idempotency, rate limits, or database transaction boundaries.
Claude Opus 5.5 and GPT-6 Astra can assist with backend architecture and implementation, but developers should evaluate them against realistic requirements. Useful tests include API contract validation, concurrent requests, permission boundaries, database migration safety, and failure recovery.
Mobile App Development: Flutter and React Native
AI coding assistants can help engineers implement Flutter widgets, React Native components, state management, and API integrations. However, mobile development also requires testing on real devices, managing platform-specific behavior, handling application lifecycle events, and preparing releases for the App Store and Google Play.
For teams building cross-platform applications, AI can reduce repetitive implementation work while engineers remain responsible for application architecture, performance, and release quality.
6. Claude Opus 5.5 vs GPT-6 API Pricing: Which Is More Cost-Effective?
Pricing becomes especially important when AI is integrated into a SaaS product or used continuously by an engineering team. A single coding session may consume a modest number of tokens, but autonomous agents can repeatedly load context, call tools, generate code, and inspect results.
At published standard API rates, Claude Opus 5.5 costs $4 per million input tokens and $20 per million output tokens. GPT-6 Astra costs $10 per million input tokens and $50 per million output tokens. This means GPT-6 Astra is 2.5 times more expensive per uncached input or output token at these rates.
Example API Cost Calculation
Assume a workload processes 10 million uncached input tokens and generates 2 million output tokens. The following example excludes caching, tool fees, long-context adjustments, and other pricing variations.
Cost componentClaude Opus 5.5GPT-6 Astra10M input tokens$40$1002M output tokens$40$100Total estimated token cost$80$200
In this simplified example, Claude Opus 5.5 costs 60% less than GPT-6 Astra for the same token volume. That does not necessarily mean it costs 60% less to complete the same task. Models may use different numbers of tokens, retries, reasoning steps, and tool calls.
For production applications, businesses should measure the total cost per successful task. This includes API usage, infrastructure, external tool calls, failed attempts, and human correction time. Smaller models such as GPT-6 Sol may also be more economical for routine workloads.
7. Context Window and Long-Running Development Tasks
Context windows determine how much information a model can process within a request. Claude Opus 5.5 supports a 1-million-token context window, while GPT-6 Astra supports approximately 1.05 million tokens.
These capacities can help with large codebases, lengthy technical documentation, and workflows involving substantial context. However, a large context window does not mean a model will always use every piece of information accurately.
In software development, effective context management is often more important than simply providing more files. Relevant architecture documents, current requirements, failing tests, and affected modules are generally more useful than indiscriminately loading an entire repository.
Developers should also consider retrieval, prompt caching, repository indexing, and persistent task notes. These approaches can improve efficiency by ensuring that the agent receives the right information at the right stage of the workflow.
8. AI Code Security: Can Claude Opus 5.5 or GPT-6 Build Production-Ready Software?
Advanced coding models can generate useful implementations, but production readiness involves much more than syntactically correct code. A production application must handle authentication, authorization, data integrity, performance, observability, deployment failures, and changing business requirements.
Both Anthropic and OpenAI describe improvements in model reliability and safeguards. Nevertheless, neither model should be considered a replacement for application security testing, engineering review, or established release processes.
Common Risks in AI-Generated Code
Missing authorization: An endpoint may authenticate a user without checking whether that user can access the requested resource.
Concurrency problems: Booking, inventory, and payment operations may fail when multiple requests arrive simultaneously.
Incorrect business logic: Code may satisfy a technical prompt while violating a product-specific rule.
Unnecessary dependencies: Generated solutions may introduce packages that increase maintenance or security exposure.
Incomplete error handling: Happy-path testing can miss timeouts, retries, partial failures, and recovery requirements.
Unsafe agent permissions: Autonomous tools may be given broader access than a task requires.
Production teams should combine AI-assisted development with automated testing, dependency scanning, secret management, code review, access controls, and deployment monitoring. Critical operations such as payments, account deletion, and sensitive data access should receive additional scrutiny.
9. Claude Code vs OpenAI Codex: Which Development Workflow Is Better?
Comparing Claude Opus 5.5 with GPT-6 Astra is not exactly the same as comparing Claude Code with Codex. A model provides reasoning and generation capabilities, while a coding agent environment determines how the model accesses files, executes commands, manages permissions, and presents changes to developers.
Claude Code provides an environment for agentic coding using Claude models. It can support workflows such as repository investigation, feature development, testing, and code review. Codex provides OpenAI's coding-agent environment, allowing developers to delegate engineering tasks and review proposed changes.
For a fair comparison, developers should use the same repository, task description, success criteria, and testing requirements. They should measure completed tasks, accepted code changes, elapsed time, tool usage, and the amount of human intervention required.
A developer already using one environment may benefit more from its workflow integration than from switching to another tool solely because of a benchmark difference. The best coding assistant is the one that improves verified engineering output within the team's existing development process.
10. Real-World Development: What AI Model Benchmarks Cannot Tell You
Software engineering benchmarks measure useful capabilities, but real products introduce constraints that are difficult to represent in isolated tests. Applications must satisfy business rules, support customers, integrate with external systems, and remain maintainable after launch.
At Next Level Software, our work on AI-enabled products illustrates why the surrounding engineering architecture matters as much as the model itself.
Example: ALIFF AI Stylist Application
Our ALIFF AI stylist case study demonstrates how AI functionality becomes part of a larger product experience. The application combines AI-generated styling recommendations with a digital wardrobe, clothing tagging, user feedback, business-rule constraints, caching, and quota management.
These capabilities highlight an important distinction between a successful AI demonstration and a reliable AI-powered application. A model may generate a useful recommendation, but the application must still manage user preferences, enforce product rules, control API consumption, and deliver a consistent experience.
This case study is not presented as a benchmark of Claude Opus 5.5 or GPT-6 Astra. Instead, it illustrates the engineering requirements that remain relevant regardless of which model powers the application.
Example: AI-Powered SaaS Products
Imagine a SaaS platform that uses an AI agent to process customer requests, update internal records, and recommend follow-up actions. The model is only one component of the solution. The system also requires identity management, database access policies, workflow orchestration, monitoring, and mechanisms for correcting errors.
A model with excellent reasoning may still cause problems if the surrounding system permits unrestricted actions or fails to validate outputs. This is why AI application development should be treated as a complete software engineering discipline rather than simply connecting an API to a user interface.
11. Vibe Coding vs Professional Software Engineering in 2026
Vibe coding has made software prototyping more accessible. Founders and developers can describe an idea in natural language and use AI tools to generate interfaces, features, and working demonstrations. This can shorten the time needed to explore a product concept.
However, rapidly generated applications may accumulate technical debt when developers do not verify the architecture, data model, security boundaries, or operational behavior. A prototype that works for a demonstration may require substantial additional engineering before it can support paying customers.
Claude Opus 5.5 and GPT-6 Astra can both support AI-assisted coding workflows, but neither removes the need for clear requirements and technical ownership. The distinction is not whether a human or AI writes every line of code. It is whether the resulting software has been designed, tested, and reviewed for its intended purpose.
For startup founders, AI can be especially useful during early product validation. Once the product begins handling real customers, payments, or sensitive information, the development process should become more structured. Our approach to MVP development focuses on building a usable first product without overlooking the foundations needed for future growth.
12. Should Developers Use Claude Opus 5.5 and GPT-6 Together?
One of the most practical strategies in 2026 is to avoid relying on a single model for every task. Different development activities have different requirements for reasoning, speed, cost, and reliability. A multi-model workflow allows teams to choose a suitable model for each stage.
For example, an engineering team could use a lower-cost model to classify incoming bug reports, Claude Opus 5.5 to investigate complex repository changes, and GPT-6 Astra to independently review a difficult architectural decision. The proposed changes would still pass through automated tests and human approval.
However, using multiple models is not automatically better. It introduces integration complexity, additional API costs, and possible inconsistencies between model outputs. Teams should adopt model routing only when evaluations show that it improves measurable outcomes.
A Practical Model Selection Framework
Development taskRecommended evaluation approachComplex codebase refactoringTest Claude Opus 5.5 and GPT-6 Astra on the same repositoryAdvanced reasoning and architectureEvaluate GPT-6 Astra alongside Claude Opus 5.5Long-running coding agentsCompare task completion, retries, and intervention ratesRoutine code generationStart with lower-cost models and escalate when neededHigh-volume business automationOptimize for cost per successful workflowSecurity-sensitive changesRequire independent testing and human approvalProduction AI integrationsEvaluate model quality, latency, cost, and operational controls
13. How to Test Claude Opus 5.5 vs GPT-6 on Your Own Project
Rather than selecting a model based only on public benchmarks, development teams should create a small internal evaluation using realistic tasks from their own software environment. The goal is to measure which model produces the best verified outcomes under comparable conditions.
Select representative tasks. Include feature development, debugging, refactoring, tests, and API integration work.
Define acceptance criteria. Specify expected behavior, permitted file changes, test requirements, and security constraints.
Use comparable environments. Keep repository state, available tools, and task instructions as consistent as possible.
Measure task success. Record whether the implementation passes automated tests and meets the requirements.
Measure engineering effort. Track execution time, retries, tool calls, token usage, and human corrections.
Review code quality. Evaluate maintainability, scope discipline, security, and compatibility with the existing architecture.
Calculate total cost. Compare successful outcomes rather than only the published price per token.
For more reliable results, repeat tasks across multiple runs and avoid drawing broad conclusions from one successful demonstration. Model performance can vary between attempts, and differences in agent tooling can affect the outcome.
14. Final Verdict: Claude Opus 5.5 or GPT-6 in 2026?
Claude Opus 5.5 and GPT-6 Astra are both serious options for modern software engineering. Claude Opus 5.5 combines long-context capabilities, agentic coding features, and comparatively lower standard API token pricing. GPT-6 Astra offers advanced reasoning, strong published coding benchmark results, and integration with OpenAI's developer and agent tooling.
Choose Claude Opus 5.5 for evaluation when cost-efficient frontier coding, long-running development tasks, repository investigation, and agent orchestration are central requirements.
Choose GPT-6 Astra for evaluation when the task demands advanced reasoning, complex tool execution, and the capabilities available within OpenAI's ecosystem. Its higher API cost makes careful measurement particularly important.
Consider lower-cost models or a multi-model strategy when building high-volume AI applications, routine automations, or development workflows where every task does not require maximum reasoning capability.
The most important lesson is that choosing a powerful AI model does not automatically produce reliable software. Clear requirements, strong architecture, automated tests, secure integrations, and experienced engineering oversight remain essential.
For businesses building AI-powered products, the better question is not simply whether Claude or GPT-6 can generate more code. It is which model and development process can deliver a dependable product at a sustainable cost.
Frequently Asked Questions
Is Claude Opus 5.5 better than GPT-6 for coding?
Neither model is universally better for every coding task. Claude Opus 5.5 offers advanced coding capabilities at lower standard API token prices than GPT-6 Astra. GPT-6 Astra demonstrates strong published performance on difficult software engineering benchmarks. Teams should compare both models using their own repositories, tests, and acceptance criteria.
Which AI model is better for autonomous AI agents?
Both Claude Opus 5.5 and GPT-6 Astra support advanced agentic workflows. Claude emphasizes long-running tasks, planning, and subagent coordination, while GPT-6 Astra provides advanced reasoning and integration with OpenAI's tools. Agent reliability also depends on orchestration, permissions, monitoring, and human approval.
Is GPT-6 Astra more expensive than Claude Opus 5.5?
Yes, based on published standard API token prices. GPT-6 Astra costs $10 per million input tokens and $50 per million output tokens, compared with $4 and $20 for Claude Opus 5.5. Actual task costs depend on token usage, caching, retries, tools, and execution efficiency.
Can Claude Opus 5.5 and GPT-6 build complete applications?
Both can assist with substantial portions of application development, including frontend components, backend APIs, database changes, and tests. However, complete production applications also require architecture validation, security review, integration testing, deployment, and ongoing maintenance.
Which is better: Claude Code or OpenAI Codex?
Claude Code and Codex are development environments rather than just models. Their effectiveness depends on repository access, tools, task execution, review workflows, and the models being used. Developers should compare them using identical engineering tasks and measurable success criteria.
Is Claude Opus 5.5 suitable for large codebases?
Yes. Claude Opus 5.5 supports a 1-million-token context window and is designed for complex software engineering tasks. However, relevant context selection, repository navigation, and verification remain important even with a large context window.
Should startups use AI-generated code for an MVP?
AI-generated code can accelerate MVP development, particularly during prototyping and early validation. Before launching to real customers, startups should review security, database integrity, architecture, integrations, and operational reliability.
Will AI coding agents replace software developers?
AI agents can automate an increasing amount of implementation and investigation work, but software development also involves business decisions, architecture tradeoffs, product requirements, security accountability, and operational responsibility. Human engineering oversight remains important for reliable production systems.
Build Reliable AI-Powered Software With Next Level Software
Choosing between Claude Opus 5.5 and GPT-6 is only one part of building an AI-powered product. The larger challenge is designing an application that integrates AI effectively, controls operational costs, protects user data, and continues to work reliably as usage grows.
Next Level Software helps businesses design and develop AI-assisted web and mobile applications, including intelligent assistants, automation workflows, recommendation systems, and custom AI integrations.
If you are planning an AI-powered SaaS platform, mobile application, or business automation system, discuss your project with Next Level Software to explore the right technical approach for your requirements.