What Is Jev AI? Why TypeSafe’s New Model Is Built to Decide, Not Chat
TypeSafe AI’s Jev takes a different approach to artificial intelligence: fast, typed decisions for software workflows instead of another stream of generated text.
Sections
For the last few years, most of the artificial intelligence industry has been focused on models that generate something: an answer, an email, an image, a piece of code, a summary or a plan. The assumption has often been that if a model becomes better at generating language, software can eventually use that intelligence to automate more work.
Jev AI takes a noticeably different approach. Instead of trying to become another chatbot, TypeSafe AI has built Jev around a narrower question: what if software needs an AI model to make a decision rather than write an answer?
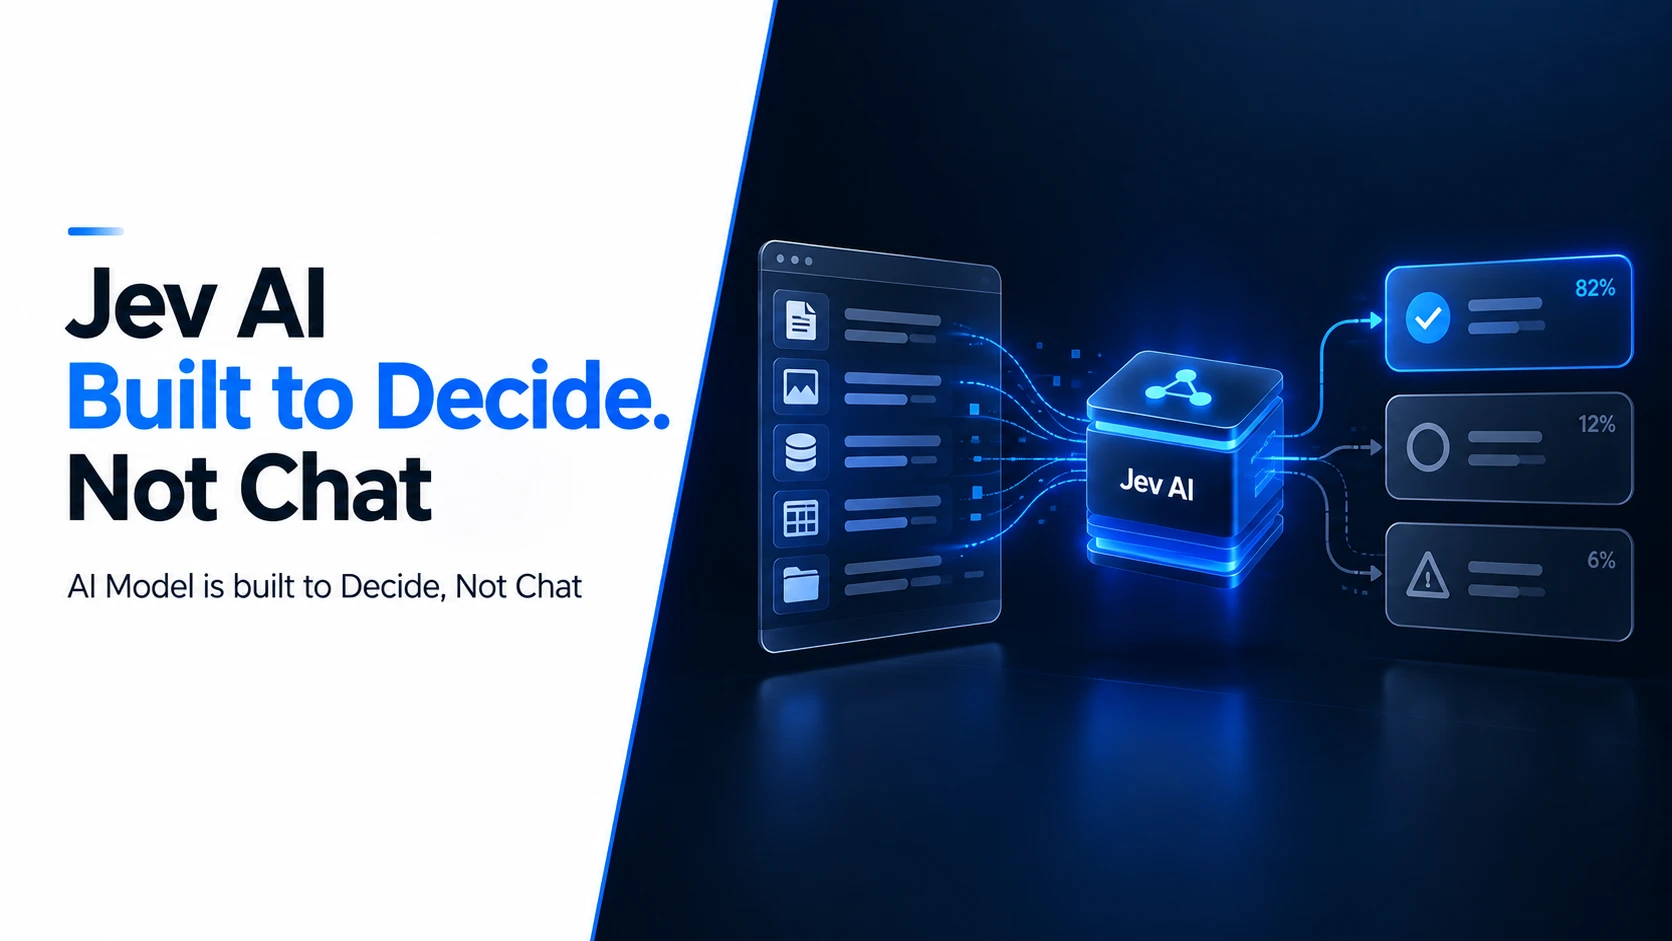
TypeSafe introduced Jev on September 15, 2026 as its first “System One Model.” The company describes the model as a machine-oriented intelligence layer that accepts unstructured application state and returns structured, typed decisions with probabilities and confidence information. In practical terms, Jev is designed to behave less like a conversational assistant and more like an intelligent function that can be inserted into an application workflow.
That distinction makes Jev interesting for developers, founders and businesses exploring AI automation. The important question is not whether Jev replaces large language models. It is whether a different type of model can solve some of the small, repeated decisions that increasingly sit between AI models, software tools and business workflows.
What is Jev AI?
Jev AI is a model developed by TypeSafe AI for structured decision-making inside software. According to TypeSafe's launch announcement, Jev takes unstructured information as input and returns predefined structured values accompanied by probabilities and confidence scores.
A traditional generative AI interaction might ask a model to read a support message and explain which department should handle it. The model could generate a paragraph such as, “This appears to be a billing issue, so I recommend sending it to the finance team.” The application then needs to interpret that text, extract the useful decision and make sure the result matches an expected format.
Jev is designed for a different interaction. The software can define the valid destinations in advance and ask the model to decide among them. Instead of generating an explanation, the result can be a defined value such as billing, together with information about how confident the model is in that decision.
That sounds like a relatively small difference, but it changes the role of AI inside the application. The model is no longer primarily creating content for a person to read. It is providing a value that another piece of software can use immediately.
Why TypeSafe calls Jev a “System One Model”
The name comes from the distinction between fast and deliberate thinking popularized by Daniel Kahneman's Thinking, Fast and Slow. TypeSafe uses “System One Models” to describe models optimized for fast decisions rather than extended generation and reasoning.
The company describes Jev as its first implementation of this idea. Rather than generating output token by token, TypeSafe says Jev can evaluate structured questions in parallel and return typed values. The company also introduced a training approach it calls Reinforcement Learning for Calibrated Decisions, or RLCD, which is intended to optimize the model around decision quality and useful estimates of uncertainty.
This is an important distinction from simply asking an LLM to return JSON. Structured-output features in existing LLMs are already extremely useful, and they can make generative models much easier to integrate into software. Jev's argument is more fundamental: if the job only requires choosing, scoring or classifying something, why use a model architecture centered on generating arbitrary strings at all?
Jev AI vs a traditional LLM
Jev and conventional LLMs overlap in the fact that both can interpret complex language and context, but they are optimized for different outputs. That means the useful comparison is not necessarily which model is universally “better.” It is which model shape matches the job the application actually needs to perform.
Area Jev AI Traditional Generative LLM Primary output Typed decisions, scores and probabilities Generated text, code or structured text Typical use Classification, routing, scoring and workflow branching Conversation, writing, reasoning, coding and content generation Output possibilities Defined by the application in advance Potentially open-ended Software integration Designed for direct machine consumption Often requires structured-output handling, validation or parsing Uncertainty Probability and confidence are part of the model's design Confidence may require additional evaluation or application logic
The trade-off is clear. Giving up open-ended generation removes many things people value about modern AI. Jev is not intended to write a proposal, generate application code, explain a complicated concept or have a long conversation with a customer. Its value depends on having a decision whose possible outputs can be constrained in advance.
Why speed and cost are part of the Jev story
TypeSafe's launch figures position Jev as an unusually inexpensive and fast intelligence layer. The company currently lists input pricing at $0.042 per million tokens and describes output as free because Jev is not generating a conventional stream of output tokens. TypeSafe also reports approximately 70–500 milliseconds of end-to-end response time in its environment.
Those numbers are TypeSafe's own published figures rather than independent NLS benchmarks, and they should be monitored as the service develops. The more important point is what the economics could enable. A business may be comfortable paying for an LLM to generate a detailed answer occasionally, but an autonomous workflow may need to make dozens or hundreds of small decisions while completing a task.
Consider an AI agent deciding which tool to use, whether a result is relevant, whether a task should be retried, whether an action looks risky and whether a human should review the result. If each of those decisions requires a relatively expensive multi-second generation, latency and model cost can accumulate quickly. A cheaper decision layer creates the possibility of using intelligence much more frequently inside the workflow.
Where Jev could fit inside AI agents
This may be one of the most interesting applications for Jev. Modern AI agents do more than generate answers. They inspect information, choose tools, call APIs, evaluate results, recover from errors and decide what to do next. We discussed this broader move from AI answers toward real workflows in our guide to AI agents for service businesses.
An agent therefore contains many small decision points. Should it search the knowledge base or the CRM? Did the previous tool call solve the problem? Is the customer asking about billing, technical support or cancellation? Is the result reliable enough to continue automatically? Should another model be called? Does this action need human approval?
A generative model can make all of those decisions, but that does not mean a generative model has to make all of them. An architecture could use a powerful LLM for tasks requiring language generation or deeper reasoning while using a decision-oriented model for repetitive routing, classification, verification or scoring.
This also complements infrastructure such as Model Context Protocol rather than replacing it. As we explained in our article on MCP and the API layer for AI agents, MCP helps AI applications discover and interact with external capabilities. A decision model addresses a different question: given the current state and available options, what should the software do next?
Potential Jev AI use cases
The most natural Jev use cases are situations where an application already knows the possible actions but ordinary rules are too rigid to interpret messy real-world information. That creates a space between deterministic software and open-ended generative AI.
Customer-support routing: Read an incoming message and select the appropriate support queue.
Lead qualification: Evaluate an enquiry and assign it to a defined lead category or priority level.
Agent workflow decisions: Decide whether an AI agent should continue, retry, escalate or select another tool.
Content classification: Categorize large volumes of text against predefined labels.
Recommendation systems: Score or rank candidates according to defined criteria before other product logic is applied.
Verification and guardrails: Evaluate whether another AI output meets specific requirements before allowing a workflow to continue.
Operational triage: Turn incoming records, tickets or events into structured priorities that existing software can process.
The pattern connecting these examples is important. The application does not need the AI to invent the next business process. The possible outcomes already exist. What the software needs is a flexible way to choose among them using information that would be difficult to handle with a large collection of traditional if-statements.
Typed output does not mean the decision is automatically correct
One part of the Jev discussion needs careful interpretation. TypeSafe emphasizes that Jev cannot produce the kind of free-form hallucination associated with generative text because its possible output types are defined in advance. If an application provides five valid categories, Jev cannot suddenly invent a sixth category or return an unexpected paragraph instead of the requested value.
That is valuable for software reliability, but it does not mean every decision will be correct. A model can choose the wrong valid category. It can misunderstand ambiguous input. It can have high confidence in a decision that does not match the application's real-world requirements. Structured output protects the interface between the model and the software; it does not eliminate the need to test whether the underlying judgment is good enough.
Production teams therefore still need representative evaluation data, confidence thresholds, monitoring, failure handling and human escalation. If a low-risk support ticket is routed incorrectly, the consequence may be minor. If the same architecture is used for a financially or operationally significant decision, the threshold for automation should be much higher.
The bigger trend: AI architecture is becoming more specialized
The most important thing about Jev may eventually be larger than Jev itself. AI applications are beginning to look less like “one model connected to an interface” and more like systems containing several specialized layers.
A production application may use deterministic code for rules that should never vary, a language model for generation and reasoning, retrieval for trusted information, a decision model for classification or routing, APIs for real-world actions and human review for decisions where uncertainty remains too high. Different kinds of intelligence can be used for different parts of the same workflow.
This is already an important principle in AI-assisted application development. The model is only one component of the product. Data access, business logic, validation, permissions, costs, monitoring, fallbacks and the surrounding user experience determine whether the AI capability actually works in production.
What our ALIFF project illustrates about production AI
ALيفF was not built using Jev, so it should not be treated as a Jev implementation. It does, however, demonstrate the broader architectural principle behind this discussion. In our ALIFF case study, generative AI is only one part of the product.
The application combines AI outfit generation with a modesty-rule layer, a digital wardrobe, automated clothing processing, stylist interactions and user feedback through actions such as accept, swap and reject. The AI layer also has practical engineering concerns around quotas, caching and streaming.
The lesson is that production AI rarely succeeds because a model was connected to an API and asked to handle everything. Reliable products define what the model should do, what ordinary software should control and where business-specific rules need to override or constrain the intelligence.
Jev approaches that same problem from another direction. Instead of asking a general-purpose generative model to behave like predictable application logic, it is trying to provide a model whose output is designed to fit directly into software logic from the beginning.
Should businesses start using Jev AI?
Jev is new, so teams should approach it as a technology to evaluate rather than assume that launch benchmarks automatically translate into production results. The right starting point is a narrow workflow where the expected answers are already known and where performance can be measured objectively.
A good candidate might be support-ticket routing. A business could collect a representative historical dataset, define the correct categories, evaluate Jev against known answers, test confidence thresholds and compare its latency, cost and accuracy with the existing solution. Low-confidence decisions could continue to a human or another model instead of being automatically accepted.
This creates a controlled path from experimentation to production. If the model performs well, its responsibility can gradually expand. If it does not, the team learns that before putting an important business workflow at risk.
Jev is likely to be less appropriate when the application needs open-ended writing, detailed explanations, complex conversational interactions or outputs that cannot be defined before the request. Those remain areas where generative language models have an obvious advantage.
What Jev AI means for software teams
The arrival of Jev adds another question to AI architecture decisions. Instead of only asking, “Which LLM should we use?”, teams may increasingly ask, “Does this part of the workflow need generation at all?”
Some parts of an application need creativity and flexible language. Some need deeper reasoning. Some need access to tools. Some need deterministic rules. And some simply need a fast judgment between several valid options.
If specialized decision models prove reliable enough, software teams may start reserving expensive generative intelligence for the tasks that actually require it while using smaller, faster or differently designed models for the thousands of decisions happening around those tasks.
That could make AI applications cheaper and faster, but potentially more importantly, it could make their architecture easier to control. Instead of one model having broad responsibility for interpreting, deciding, generating and acting, developers can design explicit boundaries around each part of the workflow.
Final thought
Jev AI is interesting because it challenges one of the assumptions that has shaped the generative AI boom: that increasingly capable text-generation models should become the intelligence layer for almost everything. TypeSafe is proposing another model category in which intelligence can be exposed more like a software primitive—a structured decision with known possible outputs and an estimate of uncertainty.
Whether “System One Models” become a major category will depend on how Jev performs outside launch demonstrations and benchmarks, how easily teams can evaluate it on their own data and whether its speed and economics remain attractive as usage grows. The model is still new, and those questions deserve real production evidence rather than hype.
For software teams, however, the architectural idea is already worth paying attention to. Building useful AI products is increasingly about choosing the right kind of intelligence for each part of the system rather than asking a single model to do everything.
If you are exploring an AI product, agent workflow or an AI feature inside existing software, Next Level Software can help you design the surrounding architecture, controls and integrations through our AI-assisted application development service. When the AI is part of a real business workflow, choosing the model is only the beginning.
Keep reading
What Is MCP? Why It Is Becoming the API Layer for AI Agents
Model Context Protocol gives AI agents a standard way to connect with tools and data. Learn how MCP works, why it matters, and where it fits in AI products
Abdullah · · 15 min read
ChatGPT Astra vs Claude Fable 5.1: Which AI Model Is Better in 2026?
GPT-6 Astra and Claude Fable 5.1 are both frontier AI models. We compare coding, agents, reasoning, context, pricing, and practical business use to see where each one wins.
Abdullah · · 18 min read
AI Can Write the Code. Who Reviews the Software?
AI can generate code faster than teams can review it. As coding agents become part of everyday development, engineering judgment, testing, security, and accountability matter more—not less.
Abdullah · · 16 min read